Search is no longer “just a box.” It behaves like a product surface, and users feel it immediately when it is slow, inaccurate, or quietly costly through things like timeouts, empty results, or answers that miss the mark. For technical teams, that changes the job. Retrieval quality, latency, and cost are now part of the user experience, so they need to be engineered and measured, including p95 and p99 latency.
Most teams have also transitioned from past single-mode search. The current practical baseline is hybrid retrieval, where keyword matching handles exact terms and identifiers, and semantic matching helps with natural language and longer queries that require full context retention. Filters and facets keep this hybrid system under control by enforcing constraints and making results predictable.
This whitepaper lays out a production-ready blueprint for AI-powered search. It walks through the full stack, from ingestion and enrichment to hybrid indexing and retrieval, recommendations, and RAG interfaces that stay grounded in retrieved sources. It also covers the work that makes these systems dependable in the real world: observability, governance using secured API keys and per-record filtering, cost controls, and lifecycle management using explicit expiration metadata and soft-delete flags. Algolia NeuralSearch combines keyword and vector retrieval, while filters and facets enforce constraints. The paper also covers rules and synonyms, analytics and A/B testing, Recommend, and operational patterns like partial updates and atomic index cutovers using copy or move index operations.
Search quality as a user-visible feature
Search quality is a crucial metric. You see it in what people actually do: fewer retries, higher conversion, faster issue resolution, and whether users trust the results. That is why this paper treats retrieval like a product surface and measures it the same way, through relevance, latency, and cost.
In practice, users feel search quality through:
- Getting to the right result on the first try, with fewer reformulations
- Seeing results that respect constraints like availability, region, compliance, and role-based access
- Getting AI answers that stay grounded, with citations that point to the right source and the right section
Why p95 and p99 latency, relevance, and cost must be engineered
AI-powered search is rarely a single query that returns results and ends there. It is a pipeline, and each stage you add can slow things down or make performance less predictable. That is why this section treats quality, latency, and cost as product features, and why it pushes teams to design around p95 and p99 performance, not just averages.
A practical way to engineer this is to define a latency budget per stage:
- Retrieval budget (hybrid search, filters, facets)
- Optional reranking budget
- Optional generation budget for RAG
- Observability budget for logging and metrics
The role of hybrid retrieval in modern AI search architectures
Single-mode systems fail in predictable ways:
- Lexical systems are precise for SKUs and exact names, but weak for natural language and exploratory intent
- Pure semantic systems surface related results without hard constraints, and they can ignore critical business requirements like availability and compliance
Hybrid retrieval combines lexical precision with semantic recall, then uses filters and facets to keep results accurate and business-valid.
Algolia serves here as the primary reference implementation for a production-grade AI search stack. The goal is to show how modern hybrid search is assembled in practice using a concrete platform with the operational building blocks, such as ingestion pipelines, governance controls, observability, and adjacent AI or data tooling.
Modern search stack reference architecture
This section walks through a modern reference architecture for AI-powered search, starting with ingestion (crawling or ETL - Extract, Transform, Load) and enrichment, then moving into hybrid indexing and retrieval. It also covers optional layers like reranking and recommendations, and shows how RAG can generate answers that stay grounded in retrieved sources.
Ingestion and data acquisition
Crawling, connectors, and ETL pipelines for ingestion
Ingestion works best when you pick the approach that matches where your data lives. Use crawlers when the source is primarily web content or documentation, connectors when data sits inside commerce or CRM systems, and ETL pipelines when you own the upstream store and need full control over how data is extracted and published. Regardless of the method, a practical ingestion checklist stays the same: define your authoritative sources and freshness requirements, normalize fields and identifiers so records stay consistent, build repeatable runs that support backfills and replays, and separate extract, transform, and publish so each step can be debugged and improved independently.
Custom ingestion pipelines and idempotent re-ingestion patterns
Idempotency is what makes reindexing safe. Use stable objectID values and deterministic transforms so re-running the pipeline produces the same records for the same inputs. This becomes essential when you change chunking strategy, embeddings, or schema and need a full rebuild.
Sample ingestion script (Python)
import os
import hashlib
import logging
from datetime import datetime, timezone

from algoliasearch.search.client import SearchClientSync

APP_ID = os.environ["ALGOLIA_APP_ID"]
ADMIN_KEY = os.environ["ALGOLIA_ADMIN_API_KEY"]
INDEX_NAME = os.environ.get("ALGOLIA_INDEX", "docs_index_v1")

client = SearchClientSync(APP_ID, ADMIN_KEY)
logger = logging.getLogger(__name__)

def fetch_docs_from_source():
    return [
        {
            "doc_id": "docs_payment_api",
            "version": "v3.2",
            "doc_type": "api_reference",
            "audience": "developer",
            "product": "payments",
            "paragraphs": [
                {
                    "text": "Create a payment by sending a POST request to /payments with amount and currency.",
                    "page": 1,
                    "heading_path": ["Payments", "Create payment"],
                },
                {
                    "text": "Use idempotency keys to prevent duplicate payment creation during retries.",
                    "page": 1,
                    "heading_path": ["Payments", "Create payment"],
                },
            ],
        },
        {
            "doc_id": "docs_refunds_guide",
            "version": "v1.8",
            "doc_type": "guide",
            "audience": "merchant",
            "product": "refunds",
            "paragraphs": [
                {
                    "text": "Refund requests can be submitted from the dashboard or through the refunds API.",
                    "page": 2,
                    "heading_path": ["Refunds", "Submitting a refund"],
                }
            ],
        },
    ]

def stable_object_id(doc_id: str, chunk_id: str) -> str:
    raw = f"{doc_id}:{chunk_id}".encode("utf-8")
    return hashlib.sha256(raw).hexdigest()

def to_record(doc_id: str, chunk_id: str, text: str, meta: dict) -> dict:
    now = int(datetime.now(timezone.utc).timestamp())
    return {
        "objectID": stable_object_id(doc_id, chunk_id),
        "doc_id": doc_id,
        "chunk_id": chunk_id,
        "text": text,
        "updated_at": now,
        **meta,
    }

records = []

for item in fetch_docs_from_source():
    doc_id = item["doc_id"]
    version = item["version"]

    for idx, paragraph in enumerate(item["paragraphs"]):
        meta = {
            "doc_type": item.get("doc_type", "kb"),
            "audience": item.get("audience", "public"),
            "version": version,
            "product": item.get("product", "unknown"),
            "page": paragraph.get("page"),
            "heading_path": paragraph.get("heading_path", []),
        }
        records.append(to_record(doc_id, f"p{idx}", paragraph["text"], meta))

if not records:
    logger.warning("No records generated for indexing, skipping publish.")
else:
    try:
        response = client.save_objects(
            index_name=INDEX_NAME,
            objects=records,
        )
        client.wait_for_task(
            index_name=INDEX_NAME,
            task_id=response.task_id,
        )
        logger.info("Published %d records to %s", len(records), INDEX_NAME)
    except Exception:
        logger.exception(
            "Batch publish failed for index %s with %d records",
            INDEX_NAME,
            len(records),
        )
        # In production, send to retry / replay queue or alerting system here.
        raise
This pattern supports deterministic rebuilds and safe schema evolution, which becomes especially important when you change chunking, embeddings, or schema and want a clean cutover without breaking relevance or access controls.
Enrichment and preprocessing
Enrichment can improve relevance without adding latency, as long as you do it upstream instead of at query time. When enrichment is baked into the index, retrieval stays fast, predictable, and easier to reason about.
Upstream enrichment (OCR, NER, tagging)
Enrichment is most effective when it happens before data ever reaches the index, so query-time stays fast and predictable. Common enrichments include OCR for PDFs and scans, paired with quality checks to handle noisy extraction, language detection and normalization to keep content consistent across locales, entity extraction and taxonomy tagging to improve filtering and faceting, and classification to flag sensitivity or compliance categories that affect access and governance.
Indexing layer
Storing keyword fields and vectors together enables hybrid retrieval
Indexing is where you decide what “search” can do. If the schema cannot represent constraints and intent, no amount of tuning will fix it later.
In practice, that means your index schema should include:
- Searchable text fields for lexical matching
- Metadata fields for filtering, faceting, and custom ranking
- Vector embeddings if you are supplying them upstream, or NeuralSearch capabilities if you rely on platform embeddings
Index design as a determinant of recall ceiling
Index design sets the recall ceiling. Decisions that matter:
- Granularity (product-level records vs chunk-level records)
- Field selection (what is searchable vs only displayed)
- Normalization (consistent category paths, units, attribute naming)
- Stable identifiers and deduplication strategy
For docs, chunking and anchors determine citation quality. For commerce, attribute normalization determines facet usability and filter stability.
Attributes for faceting, filtering, and ranking
Treat facets and filters as first-class. Define:
- Attributes for filtering (hard constraints like in_stock, tenant_id)
- Attributes for faceting (navigation like brand, category_path)
- Attributes for ranking (signals like popularity, freshness)
Retrieval and ranking
Hybrid retrieval flow (keyword plus vector)
The stack should support hybrid retrieval, then structured constraints, then tuning.
A practical query-time flow:
- Apply hard constraints first, especially tenancy and ACLs
- Run hybrid retrieval
- Apply business tuning, including rules, synonyms, and custom ranking
- Add reranking only if the p95 budget permits it
Filters and facets as recall stabilizers
Filters and facets keep semantic recall accurate. The outline explicitly calls these out as stabilizers.
Example query (JavaScript)
import { algoliasearch } from "algoliasearch";

const client = algoliasearch(
  process.env.ALGOLIA_APP_ID,
  process.env.ALGOLIA_SEARCH_API_KEY
);

const response = await client.searchSingleIndex({
  indexName: "products",
  searchParams: {
    query: "camping cooler for drinks",
    filters: "inStock:true AND region:US AND price_range:mid",
    facetFilters: ["category:Outdoor"],
    hitsPerPage: 20,
  },
});

const hits = response.hits;
Optional reranking and recommendation stages
Reranking and recommendations are best treated as optional layers on top of a stable retrieval foundation. They can improve top-of-page precision and discovery, but only when they are budgeted, measurable, and applied selectively. The safest approach is to enforce eligibility filters first, then apply reranking only when latency and traffic patterns justify it.
Use reranking when:
- You need higher precision in the top results
- You can afford the latency within p95 targets
Use Recommend when:
- You want discovery beyond the initial query
- You want complementary items such as “related products” and “frequently bought together”
Pattern 1: Dynamic Re-Ranking in Algolia
Algolia’s Dynamic Re-Ranking can adjust the ordering of results, and you can control it per query with the enableReRanking parameter. This is useful when you want a precision boost at the top of the list while keeping retrieval and constraint logic unchanged.
Pattern 2: An external reranker stage
Some teams run an additional model after retrieval to rerank the top candidates. This can work, but it must be optional and gated by latency budgets because it adds network and compute overhead. Eligibility filters and ACL enforcement should happen before reranking so the reranker never sees disallowed candidates.
When to use reranking
- The query is ambiguous or exploratory, and top-of-list precision matters
- You can afford the latency within your p95 and p99 targets
When to use Recommend
You want discovery beyond the initial query, such as related items or frequently bought together modules.
Code example: controlling Dynamic Re-Ranking per query
import { algoliasearch } from "algoliasearch";

const client = algoliasearch(
  process.env.ALGOLIA_APP_ID,
  process.env.ALGOLIA_SEARCH_API_KEY
);

const query = "running shoes";
const commonSearchParams = {
  filters: "tenant_id:acme AND region:us",
  hitsPerPage: 20,
};

let hits = [];

try {
  const response = await client.searchSingleIndex({
    indexName: "products",
    searchParams: {
      query,
      ...commonSearchParams,
      enableReRanking: true,
    },
  });

  hits = response.hits;
} catch (error) {
  console.error("Search with re-ranking failed, falling back to standard retrieval", error);

  const fallbackResponse = await client.searchSingleIndex({
    indexName: "products",
    searchParams: {
      query,
      ...commonSearchParams,
      enableReRanking: false,
    },
  });

  hits = fallbackResponse.hits;
}
Latency budgets in practice
A latency budget only works when it is explicit and enforced. Treat the search request as a chain of stages, then assign each stage a maximum time and a fallback. For example, you can reserve a fixed budget for retrieval, a smaller optional budget for reranking, and a capped budget for generation if you are running RAG.
The most reliable way to keep p95 stable is to make earlier stages predictable. Following the retrieval rules above, enforce tenant and ACL filters before candidate expansion, then manage latency with facets, caching, and optional reranking. This turns latency into a product decision rather than an engineering accident. Teams can communicate tradeoffs clearly, and they can measure whether the tradeoff improved outcomes like first-query success and reformulation rate.
Generation and feedback loop
Generation is not a replacement for retrieval. It is an interface layer that must remain grounded in retrieved results, with citations and refusal behavior when coverage is weak.
Retrieval-augmented generation (RAG) grounded in search results
A safe RAG pattern:
- Retrieve top chunks with strong filters and version constraints
- Build a context pack with short passages and metadata (url, anchor, version)
- Generate only from retrieved passages
- Require citations for key claims
- If coverage is low, do not generate an answer, return sources and refinements
Paste-ready RAG prompt contract (structured example):
System role:
You are a product support assistant. Answer only from the retrieved sources provided in the
context pack. Do not use outside knowledge. Do not infer undocumented behavior. If the sources
are weak, conflicting, outdated, or missing the requested version or product, do not guess.

Goal:
Return a grounded answer that is useful, concise, and easy to verify.

Input contract:
- user_question: the end-user’s question
- requested_version: optional version string from user context
- retrieved_sources: a list of source objects, each containing:
  - source_id
  - title
  - url
  - anchor
  - version
  - doc_type
  - passage_text
- answerability_score: high, medium, or low
- max_answer_tokens: hard output limit
- max_citations_per_claim: default 1, maximum 2

Grounding rules:
1. Use only facts supported by retrieved_sources.
2. Every material claim, step, warning, limit, or configuration must cite at least one source_id.
3. Prefer sources that match the requested_version. If version mismatch exists, state that
clearly.
4. If top sources conflict, do not merge them into one answer. Surface the conflict.
5. If answerability_score is low, refuse to answer directly and return the best sources plus
refinement suggestions.
6. If answerability_score is medium, answer only if the top sources agree and version alignment
is clear.
7. Never invent parameters, endpoints, error codes, limits, or product behavior.

Output format:
Return valid JSON with this schema:

{
  "status": "answered" | "insufficient_coverage" | "version_conflict",
  "answer": [
    {
      "step": "short actionable statement",
      "citations": ["source_id"]
    }
  ],
  "warnings": [
    "optional warning about version mismatch, weak coverage, or conflicting docs"
  ],
  "follow_up_question": "ask only if needed to disambiguate version, product, or environment",
  "suggested_filters": {
    "product": ["optional"],
    "version": ["optional"],
    "doc_type": ["optional"]
  },
  "top_sources": [
    {
      "source_id": "string",
      "title": "string",
      "url": "string",
      "anchor": "string"
    }
  ]
}

Refusal behavior:
- If the answer is not supported, set status to "insufficient_coverage".
- Leave answer as an empty list.
- Populate warnings with the reason.
- Return top_sources and suggested_filters.
- Do not fabricate a partial answer.

Token and length constraints:
- Keep the full response under max_answer_tokens.
- Prefer 3 to 5 short answer steps.
- Prefer direct quotations only when necessary and keep them minimal.

User question:
{{user_question}}

Requested version:
{{requested_version}}

Answerability score:
{{answerability_score}}

Retrieved sources:
{{retrieved_sources}}

max_answer_tokens:
{{max_answer_tokens}}

max_citations_per_claim:
{{max_citations_per_claim}}
A usable RAG prompt contract should define more than tone. It should specify the input fields, grounding rules, refusal behavior, version handling, output schema, and token limits so the generation layer can be tested, monitored, and safely degraded when coverage is weak.
Build vs. buy note for RAG orchestration
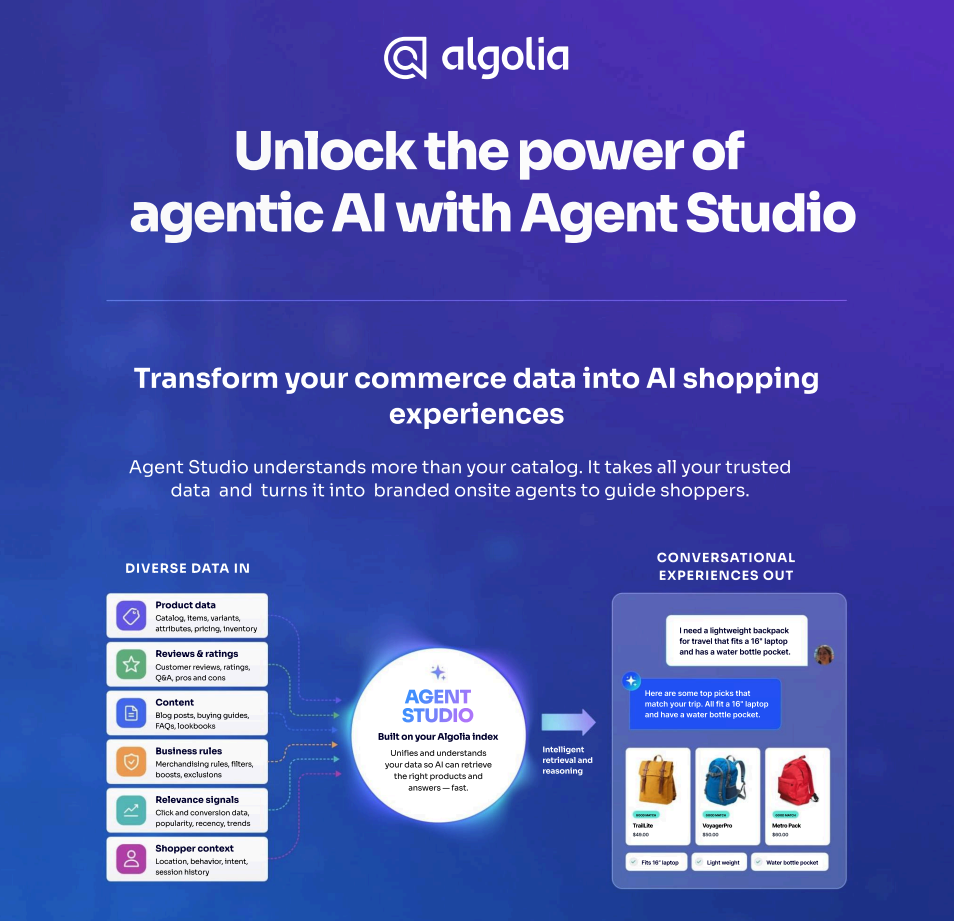
The architecture above shows the underlying pattern: retrieval, context packing, prompt assembly, citation rendering, and answerability gating. Teams that want full control may build this workflow directly. Teams that want to skip most of the orchestration work can use Algolia Agent Studio, which connects a chosen LLM to Algolia search and tools, manages the end-to-end workflow, and grounds responses in live Algolia data. For teams building broader agent workflows across systems, Algolia’s hosted MCP Server provides a governed way to expose search and recommendation capabilities to LLMs and agents.
Collecting feedback signals via analytics and insights
Feedback loops turn search into an improving system:
- Log query, filters used, and clicked results
- Track reformulations, zero-results sessions, and time-to-success
- For RAG, track answerability rate, citation coverage, citation click-through, and “no generation” events
- Use these signals to drive both tuning and content improvements, such as missing docs or missing metadata
Bill of materials: layers, components and pitfalls
Use this bill of materials to map the reference architecture to concrete Algolia components and the adjacent tools that commonly surround them in production deployments.
Common pitfalls to catch early:
- Missing stable identifiers, which makes rebuilds unsafe
- Missing ACL metadata, which makes access control inconsistent
- Faceting on uncontrolled attributes, which increases latency variance
- No rebuild and cutover strategy, which makes reindexing risky. See Lifecycle (in the table) for the operating pattern
This is the short version of the operational checklist. A fuller anti-patterns and remediation section appears later in the paper and should be used during design reviews, rebuild planning, and incident follow-up.
| Layer |
Purpose |
Algolia components |
Common adjacent tools |
| Ingestion |
Acquire data |
Crawler, connectors, API clients |
ETL / orchestration frameworks, source webhooks, CDC pipelines, queues, replay systems |
| Enrichment |
Improve content and metadata |
Index-ready record modeling |
OCR, NER, classifiers, taxonomy services |
| Indexing |
Store lexical and vectors |
NeuralSearch index design |
Schema registry, CI pipelines |
| Retrieval |
Hybrid search with constraints |
NeuralSearch, filters, facets |
API gateway, caching, feature-flag controls, query middleware |
| Tuning |
Control relevance |
Custom ranking, rules, synonyms |
Feature flags, merchandising systems |
| Optional reranking |
Improve top-K |
AI reranking stage |
Rerank models, latency monitoring |
| Recommend |
Discovery |
Recommend stage |
Personalization systems, analytics warehouse |
| RAG front end |
Grounded answers |
Retrieval results as context |
LLM provider, prompt / policy middleware, citation rendering, evaluation harness |
| Observability |
Measure and debug |
Analytics and insights |
Dashboards, logs, tracing |
| Governance |
Access and privacy |
Secured API keys, per-record filters |
IAM, DLP, audit logs, key-management and secret-rotation systems |
| Lifecycle |
Retention and rebuilds |
Expiration metadata, soft delete flags, index copy or move operations for planned cutovers, and partial updates for incremental freshness. |
Backfills, replay pipelines, backups |
Production anti-patterns and remediation
When search quality drops, it is tempting to blame the model, but the root cause is usually the data and how it is structured. Most fixes come down to improving retrieval precision, enforcing constraints like version, region, and access control, and keeping behavior stable across rebuilds.
One record for an entire PDF or long page
- What happens: citations are vague and users have to scroll to find the relevant part
- Fix: chunk by headings and paragraphs, and store anchors so retrieval can land on the right section
Chunks that are too long
- What happens: results point to the right document but the wrong passage, and answers miss details
- Fix: split chunks by subtopic boundaries and keep each chunk focused on one idea
Noisy OCR content
- What happens: embeddings match on garbage text and false positives increase
- Fix: add OCR cleaning and quality checks, and exclude low-quality extractions from indexing
Missing canonical IDs
- What happens: duplicates appear across HTML and PDF sources and ranking shifts after rebuilds
- Fix: introduce canonical IDs and lineage fields so the system can identify equivalent content across sources
Missing version and access metadata (ACLs)
- What happens: users see the wrong release or restricted content, and caching becomes unsafe
- Fix: make version and ACL fields required in every record and enforce them at retrieval time
Faceting on uncontrolled or noisy attributes
- What happens: facets become messy, cardinality explodes, and queries slow down
- Fix: normalize attributes and cap facet cardinality with controlled vocabularies and bucketed ranges
Unstable objectID values across rebuilds
- What happens: duplicates appear after reindexing and partial updates stop behaving predictably
- Fix: use stable, deterministic objectID values that do not depend on ingestion order or transient IDs
Embeddings that ignore critical structured fields
- What happens: semantic retrieval returns plausible but invalid results, like wrong region or wrong version
- Fix: apply constraints early in retrieval and ensure embedding inputs and schemas reflect key eligibility fields
Remediation (rebuild pattern)
- Re-chunk and re-index following the document chunking rules defined earlier, preserving heading_path, section_id, and deep-link anchors, then validate citation precision on sampled queries
- Add missing metadata and backfill: require version, doc_type, audience, acl_roles, backfill older records, and clearly mark deprecated versions
- Normalize attributes and control facets: standardize categories and attributes, bucket ranges like price, and remove facets that are not used
- Use atomic cutover rebuilds: build a new index, validate it with a golden set and limited live traffic, then switch in one move and keep rollback until metrics stabilize
With those failure modes in mind, the remaining sections focus on performance, cost, and rollout choices that keep the architecture stable in production.
Worked examples
This example uses a typical retail catalog where people search in two different ways. Sometimes they know exactly what they want, like “AirPods Pro 2.” Other times they are describing a need, like “running shoes for flat feet.” The aim is to keep p95 latency steady, make filtering reliable, and ultimately drive higher conversion.
Request flow (query time)
The flow below applies the earlier retrieval, filtering, and latency-budget rules to a retail search experience.
Worked query example for retail: hybrid retrieval request
import { algoliasearch } from "algoliasearch";

const client = algoliasearch(
  process.env.ALGOLIA_APP_ID,
  process.env.ALGOLIA_SEARCH_API_KEY
);

const query = "running shoes for flat feet";

const response = await client.searchSingleIndex({
  indexName: "products",
  searchParams: {
    query,
    filters: "tenant_id:acme AND region:US AND language:en AND in_stock:true",
    facetFilters: ["category_path:Shoes > Running"],
    hitsPerPage: 24,
    attributesToRetrieve: [
      "objectID",
      "title",
      "brand",
      "category_path",
      "price",
      "currency",
      "discount_percent",
      "in_stock",
      "rating_avg",
      "image_url",
      "product_url"
    ],
    facets: ["brand", "category_path", "price_bucket", "rating_bucket", "attributes.color",
      "attributes.size"]
  }
});

const hits = response.hits;
const facets = response.facets;
Record fields (minimum useful schema)
- objectID (stable SKU or product ID)
- title, subtitle, brand, category_path, description_short
- image_url, product_url
- price, currency, discount_percent
- in_stock (boolean), inventory_count (optional), availability_status
- region, language, tenant_id
- rating_avg, rating_count
- attributes (flattened attributes such as size, color, material)
- popularity_7d, sales_30d (or a single score)
- embedding (vector representation derived from title + key attributes)
Filters and facets (recommended defaults)
- Filters: tenant_id, region, language, in_stock, and any compliance tags
- Facets: brand, category_path, price_bucket, rating_bucket, attributes.color, attributes.size
Ranking and tuning knobs
- Use custom ranking for business goals: in_stock desc, popularity_7d desc, rating_avg desc, discount_percent desc (order depends on your strategy)
- Use rules for merchandising: pinned items for seasonal campaigns, promoted categories, or brand agreements
- Use synonyms carefully for category terms, and avoid broad synonyms that collapse precision
- Keep vectors and text fields aligned. If embeddings include “waterproof,” ensure your searchable fields also include that attribute
Fallback rules (latency and quality)
- If over budget, skip reranking first and return tuned hybrid results with facets
- If still over budget, reduce candidate set size and limit expensive highlighting or large payload fields
- If inventory is volatile, prefer partial updates of stock and price. If updates lag, show a lightweight “availability may vary” UI note and log it as an ingestion gap
Recommend modules
- “Related products” can use co-view or similarity signals
- “Frequently bought together” can use basket analysis and post-purchase signals
- Keep these modules under their own latency budgets, and fall back to simple category-based recommendations if needed
Docs portal: version-aware retrieval, citations, and safe RAG answerability
This example assumes a documentation portal where users ask “how do I configure X,” and expect trustworthy answers with citations. The goal is correctness, strong access control, version awareness, and clear behavior when content is missing.
Request flow (query time)
The flow below applies the earlier chunking, version-filtering, access-control, and grounded-generation rules to a documentation workflow.
import { algoliasearch } from "algoliasearch";

const client = algoliasearch(
  process.env.ALGOLIA_APP_ID,
  process.env.ALGOLIA_SEARCH_API_KEY
);

function buildContextPack(hits) {
  return hits.map((hit) => ({
    source_id: hit.objectID,
    doc_id: hit.doc_id,
    section_id: hit.section_id,
    heading_path: hit.heading_path ?? [],
    content: hit.content,
    url: hit.url,
    anchor: hit.anchor,
    version: hit.version,
  }));
}

async function retrieveChunks({ query, product, version, aclRole }) {
  const response = await client.searchSingleIndex({
    indexName: "docs_chunks",
    searchParams: {
      query,
      filters: `product:${product} AND version:${version} AND acl_roles:${aclRole}`,
      hitsPerPage: 8,
      attributesToRetrieve: [
        "objectID",
        "doc_id",
        "section_id",
        "heading_path",
        "content",
        "product",
        "version",
        "url",
        "anchor",
      ],
    },
  });

  return response.hits;
}

const hits = await retrieveChunks({
  query: "how do I configure webhook retries",
  product: "payments",
  version: "v3",
  aclRole: "developer",
});

const contextPack = buildContextPack(hits);

// Replace this with your actual LLM call.
const promptPayload = {
  user_question: "how do I configure webhook retries",
  retrieved_sources: contextPack,
  answerability_score: "high",
  max_answer_tokens: 300,
  max_citations_per_claim: 2,
};
Chunking and metadata model
- Chunk size: aim for 150 to 350 words per chunk, aligned to headings and lists.
- Required fields:
- objectID (stable chunk ID)
- doc_id, section_id, heading_path
- content (chunk text)
- product, version, language
- url, anchor (deep link to section)
- tenant_id, acl_roles (or equivalent access tags)
- updated_at (for freshness handling)
- embedding (vector for semantic retrieval)
Filters and facets
Filters: tenant_id, acl_roles, language, and when present product, version
Facets: product, version, doc_type (guide, API reference, troubleshooting), and optionally platform (web, iOS, Android)
RAG generation policy
- Only generate from retrieved chunks, and always keep citations visible
- If the user asks for steps, prefer enumerated steps copied from sources with light rephrasing, and cite the relevant section for each step
- If sources disagree by version, present the version split explicitly and cite both
Answerability and fallback rules
- If coverage is low, do not guess. Return the best passages, show filters for product and version, and recommend a refinement query
- If citations are weak, return “top sources” only and skip generation
- If the query is a known error code and retrieval returns multiple versions, ask the UI to prompt for the user’s version while showing the most common version’s sources first
Evaluation signals to log
- Query reformulation rate after the answer
- Click-through on citations and time-on-source
- “No answer generated” rate, and the top missing topics
- Version mismatch rate, where users select a different version after seeing results
Representative server-side pattern: generating a scoped secured API key
Representative server-side example
The exact implementation varies by backend runtime and key-management setup, but the pattern is the same: generate a short-lived secured search key on the server, scope it with tenant and role filters, and return it only to an authorized client.
Representative server-side pattern: generating a scoped secured API key
Generate a short-lived secured search key on the server from a parent search key, scope it with tenant and role filters, optionally restrict it to the required index, and return it only to an authorized client.
const securedApiKey = client.generateSecuredApiKey({
  parentApiKey: process.env.ALGOLIA_SEARCH_API_KEY,
  restrictions: {
    restrictIndices: ["docs_chunks"],
    filters: "tenant_id:acme AND acl_roles:developer",
    validUntil: Math.floor(Date.now() / 1000) + 3600,
  },
});
In production, pair this pattern with normal backend controls such as secret storage, key rotation, user authentication, and audit logging. Read more on Algolia’s Secured API Keys for data safety.
Hybrid search done right: lexical plus vector plus control
Why single-mode search breaks
Keyword search depends on term overlap and performs well for known-item queries like SKUs, IDs, and exact names. It performs poorly for natural language and exploratory intent, especially when catalog metadata is incomplete and users describe use cases rather than product names.
Vector search excels at semantic similarity, but it lacks hard constraints by default. Pure semantic retrieval often surfaces business-invalid results, ignores constraints like availability and compliance, and struggles with exact matches like error codes.
Hybrid retrieval architecture
A production architecture separates:
- Candidate generation (hybrid retrieval)
- Eligibility (filters, ACLs, policy tags)
- Navigation (facets and refinements)
- Tuning (ranking signals, rules, synonyms)
- Optional precision stages (reranking)
This separation improves debuggability. When a query fails, you can diagnose whether the issue is missing data, wrong filters, ranking signals, or poor embeddings.
Where approximate nearest neighbor parameters matter
If you manage your own vector layer, ANN parameters affect latency and recall. Common knobs include:
- Candidate list size, which increases recall but increases latency
- Search depth parameters, such as efSearch or similar engine-specific controls
- Filter strategy, ideally applying structured filters efficiently after ANN candidate generation
Relevance tuning and fallbacks
Tuning is where hybrid search becomes a product. You need clear rules for when lexical wins, when semantic expands, and when to refuse generation.
Biasing lexical confidence vs semantic expansion
A practical approach:
- If lexical confidence is high, such as an exact SKU match, bias lexical
- If semantic recall is low, widen semantic candidates
- Use synonyms and rules to encode business intent, not to patch broken data
Gating strategies for restricted or sensitive content
Restricted domains require explicit gating. Following the earlier eligibility rules, enforce ACL filters at retrieval time, then layer additional controls such as index separation, sensitivity tags, and sources-only behavior for high-risk requests.
Gating is not only a security mechanism. It also improves trust and reduces downstream incidents.
Core operating principles explored throughout the paper:
- Apply eligibility constraints before ranking decisions. Tenant, ACL, region, version, and policy filters should be enforced at retrieval time, not patched in later.
- Chunk to match user-visible meaning. For docs and PDFs, chunk by heading and then by paragraph or section boundaries so citations remain precise.
- Treat latency as a product budget. Keep earlier stages predictable, and degrade gracefully by skipping optional precision stages before breaking core retrieval.
- Use atomic cutovers for rebuilds. Reindex into a new target, validate it, switch once, and keep rollback available until metrics stabilize.
Indexing and chunking strategies that move the needle
Chunking and record design often matter more than model choice because they decide whether constraints can be enforced, whether citations land on the right section, and whether you can evaluate quality in a repeatable way. If you index at the wrong granularity, RAG becomes guesswork and filters start to feel unreliable. A practical rule is to make the “right” result easy to retrieve with constraints already applied. That means stable identifiers and a small set of required metadata, and chunks that follow user-visible structure like headings and sections.
Principles that apply to all domains
- Pick granularity based on user intent: Docs and PDFs should land on a paragraph or section, code and APIs should land on a symbol or error reference, and ecommerce should land on a product or variant.
- Make canonical identity non-negotiable: Use stable IDs that survive rebuilds. Without them you get duplicates, drift, broken citations, and unreliable partial updates.
- Put constraints in the record: If a constraint matters, it must be stored and filterable at retrieval time. Do not rely on application logic alone for audience, region, release, or roles.
- Chunk for meaning and citation quality: The document-specific rules for headings, paragraphs, and anchors are covered in the docs and PDFs section below.
- Design for measurement: Your schema should make it easy to measure answerability, coverage, and version alignment so you can improve systematically.
Minimum required fields:
- objectID or stable primary ID
- content (the searchable text for the chunk or record)
- doc_id or entity ID (document, symbol, product)
- chunk_id or section pointer (for chunked sources)
- version (or release identifier)
- acl_roles (or equivalent access control field)
- doc_type or entity type (guide, API ref, product, ticket)
- source or url (provenance for debugging and citations)
Document and PDF indexing
Docs and PDFs are especially sensitive to chunking because citation quality and retrieval precision depend on structural boundaries. The rules below focus on preserving headings, paragraph meaning, and deep-link anchors.
Chunk at paragraph granularity, aligned to structure
- Chunk by heading, then by paragraph boundaries inside each section
- Target size: 150 to 350 words per chunk for most content
- Preserve lists and tables as text blocks tied to the nearest heading
- Keep “procedural steps” together when possible, because splitting steps reduces usefulness
Use overlap only when necessary
- If the content uses heavy cross-references, add a small overlap of 1 to 2 sentences
- Avoid large overlaps that create near-duplicates, because they pollute recall and inflate storage
Treat headings as first-class
- Every chunk should carry heading_path, for example Setup > Authentication > API Keys
- Store section_id that maps to a deep link anchor
- Store page only when the source is a PDF and page numbers matter to users
Recommended identifiers
- doc_id: stable document identifier, for example docs_payment_api
- version: release version, for example v3.2 or 2025-10
- chunk_id: stable chunk identifier within the doc and version
- canonical_id: stable identifier across formats, for example HTML vs PDF for the same content
- source_id: ingestion source, for example crawler_html, pdf_ocr, cms_export
Lineage fields
- parent_doc_id: if content is derived from another doc
- derived_from: for example pdf_sha256:<hash> or cms_page_id:<id>
- updated_at: source last modified time
- indexed_at: time this record was indexed
Lineage lets you answer questions like “why do I have duplicates” and “which source is authoritative.”
Filtering: content category, release, and user role
Docs search usually needs filters that users do not always see but always benefit from:
- doc_type: guide, API reference, troubleshooting, release notes
- audience: developer, merchant, internal support, admin
- acl_roles: roles allowed to view this content
- version: filterable, and ideally facetable in the UI
- product or component: used for refinement and evaluation
This makes retrieval correct before any ranking happens.
Recommended record fields for docs and PDFs
Minimum recommended fields:
- doc_id, version, chunk_id, canonical_id
- page, section_id, heading_path
- doc_type, audience, acl_roles
- language, region (if applicable)
- url, anchor
- content (chunk text)
- updated_at, indexed_at
Highly useful optional fields:
- entities (error codes, product names, parameters)
- keywords (manual tags from authors)
- sensitivity (public, internal, restricted)
- embedding (vector representation)
Common mistakes in doc indexing and how to avoid them
- Indexing the whole page as one record leads to vague citations and low answerability. Fix: chunk by headings and paragraphs, preserve anchors
- Not storing version as a filterable attribute leads to mismatched answers. Fix: make version required for all doc chunks, and facet it in the UI
- As discussed in Retrieval, access constraints must be enforced at retrieval time. For docs, that means every record needs acl_roles or equivalent tags so the rule is technically enforceable
Code and API documentation
Code and API documentation needs a different approach than regular written docs. People search using things like symbol names, error codes, method signatures, parameter names, and language-specific syntax. If your indexing does not capture that structure, search results will feel inconsistent even if the content is technically there.
Chunk by symbol, not by page
- For API references, chunk by endpoint or method
- For SDK docs, chunk by class, method, function, or module
- Keep the signature with the description, examples, and errors
Keep examples close to the symbol
Examples are often what users need most. If you separate examples, retrieval will find the wrong thing. Store examples in the same record or as child records with strong lineage to the parent symbol.
Avoid duplication across versions and platforms
SDK docs often share content across versions. This can create duplicates that confuse retrieval and inflate cost.
Recommended strategies:
- Use canonical identifiers that include platform, language, and sdk_version
- Store “alias” fields when a symbol is renamed or moved packages
- Create a clear rule for which version is default when user context is missing
Schema design for code and APIs
You want the schema to support three query types:
- Exact symbol lookups
- “How do I” questions that should land on a specific method or guide
- Error-based debugging queries
For exact lookups, lexical fields matter. For “how do I,” semantic fields matter. For errors, both matter.
Recommended fields
- Identity and type:
- symbol_id, symbol_type (class, method, function, endpoint, error)
- language, platform
- package, module, namespace
- sdk_version or api_version
- Searchable content:
- signature
- description
- parameters
- returns
- examples
- errors (error codes, exceptions)
- see_also links or related symbols
- Constraints and UX:
- audience
- version
- doc_type (reference, tutorial, migration)
- url, anchor
Recommended record fields for code and API docs
Minimum recommended fields:
- symbol_id, symbol_type, language, package, sdk_version
- signature, description, examples, errors
- platform, audience, version
- url, anchor, updated_at
- embedding
Highly useful optional fields:
- deprecated (boolean) and replacement_symbol_id
- introduced_in_version, removed_in_version
- tags (auth, payments, webhooks, retries)
- entities (common config keys, header names)
Duplication prevention patterns
- Canonical symbol identity: Use symbol_id that includes stable components, for example java:com.acme.payments.Client#charge
- Version-aware defaults: If user context is missing, pick a default version, but clearly label it and provide a version facet
- Deprecation metadata: If a symbol is deprecated, retrieval should surface the replacement and guide users away from old versions
Ecommerce catalogs
Ecommerce search plays by slightly different rules. Filters need to respond instantly and changes like price or stock should appear without delay. On top of that, ranking often has to balance relevance with business goals. Chunking usually is not the deciding factor here. What really drives performance and usability is a clean schema and well-normalized attributes.
Denormalize for search
Search needs speed and simplicity at query time. Denormalize the key fields into each record:
- Product title, brand, category path
- Variant attributes like size, color, material
- Availability and pricing signals
- Region and language
Choose whether you index:
- One record per product, with variants nested or flattened fields
- One record per variant, if variants differ meaningfully in price or availability
Availability and pricing data
Availability and pricing must be filterable for correctness:
- inStock should be filterable
- region should be filterable
- price should be filterable and sortable
- price_range should be facetable, usually via bucketization
Use partial updates for inventory and price if your freshness SLO is tight.
Facets and navigation
Facets guide exploration:
- category, brand, price_range
- optionally rating_bucket, discount_bucket
- controlled attributes like color, size, material
Recommended record fields for ecommerce
Minimum recommended fields:
- product_id, variant_id, title, description
- category, brand
- price, price_range, inStock
- region, language
- popularity (or engagement signal)
- Optional: margin_bucket if you use it for ranking
Choosing an embedding strategy
Embeddings are only useful if they make the product better. Whether they actually help depends less on the model itself and more on how you index content and how you evaluate results.
Out-of-the-box embeddings vs domain-specific models
Out-of-the-box embeddings are a strong baseline for general language. Domain-specific models help when:
- You have specialized terminology (medical, fintech, legal)
- Short tokens carry meaning (error codes, product SKUs)
- You need strong multilingual or cross-language matching
A practical approach is to start with a baseline embedding model, then fine-tune only after you have strong evaluation data and stable chunking.
Dimensionality and cost management
Embedding dimension affects storage and retrieval cost. Manage cost by:
- Keeping chunk size and index granularity appropriate
- Avoiding embedding fields that do not improve retrieval
- Budgeting vector candidates and limiting reranking to needed traffic
- Measuring marginal gain from model changes before scaling them
Versioning and drift management
Embeddings drift when content changes or models change. Treat embeddings as versioned artifacts:
- Store embedding model version in metadata
- Recompute embeddings in controlled rebuilds
- Use evaluation to validate improvements before full rollout
- Keep rollback ability through the rebuild and cutover pattern described in Lifecycle
Vector database patterns in production
Vector search is only truly ready for production when it works like the rest of your system. That means it needs strong filtering, reliable ACL enforcement, a clear lifecycle plan for stale content, and a schema that can evolve without breaking things.
Unified vector and keyword indices
The simplest way to avoid surprises is to keep your keyword search and vector search in the same index. That means each record contains the text you want to search, the attributes you need for filtering and faceting, and the vector embedding. When everything lives together, retrieval stays consistent and your constraints, like tenant, region, and access control, apply the same way every time.
If you split lexical and vector infrastructure, preserve the same eligibility rules described in Retrieval, especially ACL and tenant enforcement, across both paths. If you cannot enforce the same rules in both places, you will eventually return results a user should not see, or you will return results that look relevant but are invalid for that request.
Multi-tenancy models
Multi-tenancy is a constraint problem. Patterns:
- Single index with tenant_id and secured API keys
- Multiple indices per tenant for strict isolation
- Hybrid model: shared public index plus tenant-specific overlays
Choose based on data isolation requirements, traffic patterns, and operational simplicity. Regardless of pattern, ensure tenant_id and role tags are present at the record level.
Schema evolution and resilience
Your schema will evolve, no matter how “final” it feels today. As the product grows, you will add new fields, tighten metadata, and sooner or later someone will ask for a new facet or filter. The teams that handle this well are the ones that plan for change up front, so updates stay predictable instead of turning into a disruptive migration.
A practical way to do it:
- Start with additive changes. Add new fields or new facets without breaking what already works
- Backfill in batches, then turn the feature on. Fill the new fields for existing records first, then enable filtering, faceting, or ranking that depends on them
- Validate in a staging index and switch over atomically. Build and test the new index, then swap traffic in one clean move so you avoid half-migrated behavior
- Keep the app compatible during the migration window. For a while, your application may need to work with both old and new fields until the cutover is complete
Search across structured and unstructured data
Early vs. late fusion
There are two common ways to combine structured and unstructured search. With early fusion, you keep everything in one index and one retrieval flow, mixing structured fields and text signals together. That usually makes ranking and constraints easier to manage, but it only works well if your schema is strong and consistent. With late fusion, you retrieve from multiple indices, like catalog, docs, and tickets, and then merge results in the application layer. This gives you more freedom to tune each source independently, but it also raises the bar for eligibility handling and measurement, because constraints must remain consistent across all paths. In general, early fusion is a good fit when your schema is stable and constraints are shared, while late fusion works better when sources are very different or need separate tuning.
Support and knowledge use cases
Support search should optimize for time-to-resolution:
- Chunk knowledge content for precise retrieval
- Filter by product, version, and user role
- For RAG, require citations and refuse when coverage is low
- Track deflection metrics and citation clicks to measure trust
Support search benefits heavily from enrichment, such as entity extraction for error codes and configuration keys.
Catalog and UGC blending
Blending catalog results with UGC requires guardrails:
- Separate moderation states as filterable fields
- Prevent low-quality UGC from dominating results
- Use facets to let users refine content type
- Consider separate indices with late fusion if ranking goals differ
Real-time and streaming search
Real-time search is less about a single feature and more about an operating model. When inventory, pricing, product details, or documentation changes, users expect search to reflect those changes quickly and consistently. To deliver that, you need a reliable update path from source systems into the index, clear freshness targets you can measure, and a recovery plan that works when pipelines stall or bad data slips through.
Streaming ingestion pipelines
Pipeline pattern:
- Source webhooks or CDC
- Lightweight transformer
- partial updates, batched for throughput
- Back-pressure with queues
Example partial update payload
import { algoliasearch } from "algoliasearch";

const client = algoliasearch(
  process.env.ALGOLIA_APP_ID,
  process.env.ALGOLIA_ADMIN_API_KEY
);

const { taskID } = await client.partialUpdateObjects({
  indexName: "products",
  objects: [
    {
      objectID: "prod_123",
      inStock: true,
      inventory_count: 12,
      updated_at: 1738020000,
    },
    {
      objectID: "prod_456",
      inStock: false,
      inventory_count: 0,
      updated_at: 1738020000,
    },
  ],
  createIfNotExists: false,
});

await client.waitForTask({
  indexName: "products",
  taskID,
});
Freshness monitoring & recovery
Freshness is not something you assume, it is something you measure and protect. If users expect inventory, pricing, or documentation changes to show up quickly, you need clear signals that tell you when the system is keeping up and when it is telling users outdated information.
Start by tracking a small set of metrics that reveal freshness health. Measure ingestion lag, which is the gap between when the source changes and when the index reflects that change. Track your partial update failure rate so you know when incremental updates are failing, retrying too much, or being dropped. Watch the percentage of queries that touch recently updated items, because those are the exact sessions where freshness problems show up first. For documentation, monitor deprecated content exposure, which tells you how often users land on older or deprecated versions instead of the right release.
Set alerts for ingestion lag and increasing update failures. Those are usually the first warning signs, and they tend to show up before dashboards make the problem obvious.
Also, treat recovery as part of freshness. Pipelines will stall and bad data will slip through sometimes, so the recovery path needs to be dependable. Keep replayable event logs or a backfill process so you can restore missed updates. Make transforms idempotent so reruns do not create duplicates or drift. Keep a rebuild workflow that supports atomic cutover: build a fresh index, validate it, then switch traffic in one clean step. Before switching, run a small set of high-value checks to confirm constraints, relevance, and version behavior look right.
Evaluation, experimentation, and measurement
Answerability score for RAG in documentation search
RAG evaluation in a docs portal needs more than relevance. You need a way to decide when generation is appropriate, and a way to measure whether answers remain grounded. An answerability score is a practical control that combines retrieval quality signals into a single decision. Use it to gate generation at query time, and use it as an evaluation metric over time.
Define the score from measurable components
You can compute an answerability score per query using a weighted combination of signals such as:
- Coverage: how many retrieved chunks contain the key entities from the query (feature name, error code, API name)
- Version alignment: whether retrieved chunks match the requested version, or the version inferred from user context
- Consensus: whether top chunks agree, or whether they conflict across versions or doc types
- Specificity: whether retrieved chunks include concrete procedures, parameters, or expected outputs, not only conceptual text
- Citation density: how many claims in the generated answer can be tied to a small set of retrieved chunks
Keep the model simple at first. Start with thresholds on the top-N retrieval scores and the presence of product and version metadata in the top results. As you collect data, refine the score by correlating it with outcomes such as reformulation rate, citation clicks, and user satisfaction feedback.
Use answerability to gate generation
Set simple, explicit rules for when generation is allowed. If answerability is high, generate a grounded response and include citations. If answerability is medium, only generate when the query is non-sensitive and the top sources agree, otherwise return the best sources instead of guessing. If answerability is low, do not generate at all. Return the strongest passages you have, include helpful filters like product and version, and log the query as a content or metadata gap. This kind of gating protects trust by avoiding confident answers that are not supported, and it also keeps latency and cost under control because generation is not triggered for every request.
Citation correctness checklist
Citation correctness should be evaluated as strictly as accuracy. A citation is not a decoration. It is the proof that an answer is grounded. Use the checklist below in offline review, in QA workflows, and in automated sampling.
A citation is correct only if all conditions are true
- Supports the claim: The cited chunk directly supports the specific claim it is attached to
- Matches the version: The cited chunk is from the correct product version, or the answer explicitly states the version difference
- Matches the scope: The cited chunk is about the same feature, parameter, or error code, not a similarly named concept
- Points to the right location: The URL and anchor lead to the exact section, not only the top of a long page
- Is not contradicted by a higher-priority source: If there is a conflict, the answer must surface the conflict and cite both sides, or it must prefer the authoritative doc type
- No missing required citations: Any step, configuration, limitation, or warning in the answer must have a citation
- No citation stuffing: Avoid attaching many citations to a single claim when one precise source is enough
Practical sampling method
- Sample queries across the head, torso, and tail. Include error codes, configuration tasks, and conceptual questions
- Review generated answers and label each claim as “supported” or “unsupported,” then label each citation as “correct” or “incorrect”
- Track three metrics: citation correctness rate, unsupported-claim rate, and no-generation rate
Operational guardrails
- If unsupported-claim rate rises, tighten answerability thresholds and increase chunk precision
- If citation correctness falls, improve chunking and anchors, and verify version metadata is present and filterable
- If no-generation rate rises, treat it as a content gap signal and prioritize documentation improvements or metadata fixes
Security, privacy, and governance
Security is not an extra feature you add later, it is part of the product. With search, the biggest risks usually come from constraints that are applied inconsistently and from data flows that are easy to lose track of as the system grows.
Access control and tenancy
Enforce tenancy and access with secured API keys and per-record filters.
A practical pattern:
- Store tenant_id and acl_roles on every record
- Generate scoped keys that enforce tenant filters
- Apply additional filters at query time for context, such as region and version
Privacy and PII handling
Handle privacy early, not after the fact. Redact PII upstream, avoid indexing anything you would not want retrieved, and make sure your logs are safe while still meeting audit requirements. Search often touches sensitive data, so treat it as a first-class design constraint: tag records that may contain PII, separate what is searchable from what is only displayable, avoid embedding raw PII into vectors, and put retention rules plus deletion workflows in place so you can meet compliance obligations.
Usage monitoring and auditability
It is always good to watch for misuse patterns, keep audit trails you can trust, and make sure your system is ready for compliance reviews.
Governance requires observability:
- Track query volumes by tenant and endpoint
- Monitor unusual spikes that may indicate abuse
- Log changes to ranking rules, synonyms, and schema
- Maintain dashboards for p95 latency, zero-results, and freshness lag
Balancing safety controls with p95 latency targets
Safety controls often sit in the hottest part of the request path. Secure model gateways, prompt filtering, and output moderation reduce risk, but they can also add network hops, compute time, and failure modes that quietly degrade p95 and p99 latency. Treat these controls as part of the architecture, not an add-on.
Following the retrieval and governance rules above, enforce tenant and access constraints before candidate expansion, then manage latency by bounding candidate sets and treating reranking and generation as optional budgeted stages.
Finally, define controlled degradation rules. If the request is over budget, skip reranking first. If it is still over budget, reduce context length and limit the number of retrieved passages. If coverage is low or citations are weak, do not guess. Return the best ranked results with filters and refinement suggestions. This keeps the core search experience responsive while preserving safety guarantees where they matter most.
Cost and capacity planning
Cost rarely comes from one big decision. It builds up through day-to-day choices like how granular your records are, which facets you enable, how large your candidate sets get, how often reranking runs, and how frequently you call generation for RAG. If you want predictable spend, treat these as design decisions, not last-minute fixes.
Index sizing and replication strategy
Size the index around what you truly need to retrieve and show. Smaller, cleaner records are easier to run and cheaper to scale. Replicas can help, but only when they serve a clear product purpose. Use them when you can tie them to a measurable outcome, like an alternate ranking strategy or locale-specific behavior. If a replica does not move a metric you track, it is usually not worth keeping.
Query and RAG token budgets
Budgets keep performance and spend under control. Define hard limits for the parts that tend to drift over time:
- Retrieval latency budget
- Reranking latency budget
- Generation budget, including maximum tokens and maximum context length
- Cache targets for common queries and common filter combinations
These budgets also make tradeoffs easier. Use the degradation rules defined in the latency section, for example skipping reranking first and reducing context only when necessary, instead of timing out.
Caching and query optimization
Caching is one of the most dependable ways to keep p95 stable, especially when requests repeat. Focus on caching high-frequency queries with common filter combinations and caching facet results for popular category or navigation pages. Keep ordering deterministic and parameters consistent so caches actually hit, and under load, prefer controlled degradation over timeouts.
Core optimization principles:
These optimization rules operationalize the earlier retrieval and latency principles: enforce eligibility early, keep candidate sets bounded, avoid uncontrolled facets, and reserve reranking and generation for requests that justify their cost.
Decision playbook
The following points focus on a 90-day rollout from pilot through evaluation, governance hardening, and scaling with CDC.
Days 0 to 30: Stand up the retrieval baseline
- Model index records with stable objectID, tenant and ACL metadata, version fields where needed, and facet-ready attributes
- Configure the first Algolia index and enable the minimum retrieval controls the paper depends on: searchable attributes, filters, and facets
- Load an initial corpus, validate chunking quality for docs content, and confirm that secured constraints can actually be enforced at query time
- In the dashboard, set the first relevance controls you already know you need, such as custom ranking, synonyms, and a small set of rules for obvious high-value intents
Days 31 to 60: Tune relevance and prove value
- Build golden queries for retail or docs search, then measure first-query success, reformulation, zero-results rate, and answerability where RAG is enabled
- Use Algolia Analytics and Insights to review query behavior, click behavior, and conversion signals
- Run A/B tests on meaningful changes, such as ranking updates, synonym changes, or enabling Dynamic Re-Ranking for the target index
- Keep the retrieval path bounded: verify facet behavior, candidate-set size, and whether reranking improves outcomes enough to justify its latency budget
Days 61 to 75: Harden governance and access control
- Move from broad environment access to scoped delivery using secured API keys and per-record filters
- Validate that the earlier eligibility rules, especially tenant, ACL, region, and version constraints, remain consistent in production traffic
- Add upstream privacy controls, safe logging rules, and dashboards for p95 latency, zero-results, freshness lag, and suspicious usage spikes
- For RAG experiences, lock down grounding rules, answerability thresholds, citation requirements, and no-generation behavior
Days 76 to 90: Scale freshness and release safely
- Replace bulk-only refresh with CDC or webhook-driven updates where needed
- Use partial updates for fast-changing fields such as stock, price, or freshness metadata
- Establish replayable recovery for failed updates and a rebuild path that uses index copy or move operations for atomic cutover and rollback
- Before each cutover, validate settings parity, filter behavior, ranking behavior, analytics continuity assumptions, and the top user journeys you care about most
Conclusion
Architecture determines relevance, latency, and cost. Hybrid retrieval is the production default for most modern search experiences, and data modeling sets the ceiling for quality. Systems that measure outcomes, enforce governance, and iterate with discipline outperform stacks that only optimize for novelty.
Security is a shared responsibility within an organization and among its partners. Strong access control, careful data hygiene, and continuous monitoring reduce risk, but they only work when the platform and operating model make them practical at scale. Choosing the right partner is crucial because it affects how quickly teams can deploy safely, tune relevance confidently, and keep performance stable as usage grows.
Request a demo of Algolia’s AI Search solution at algolia.com/demorequest or read more at algolia.com/blog/ai/